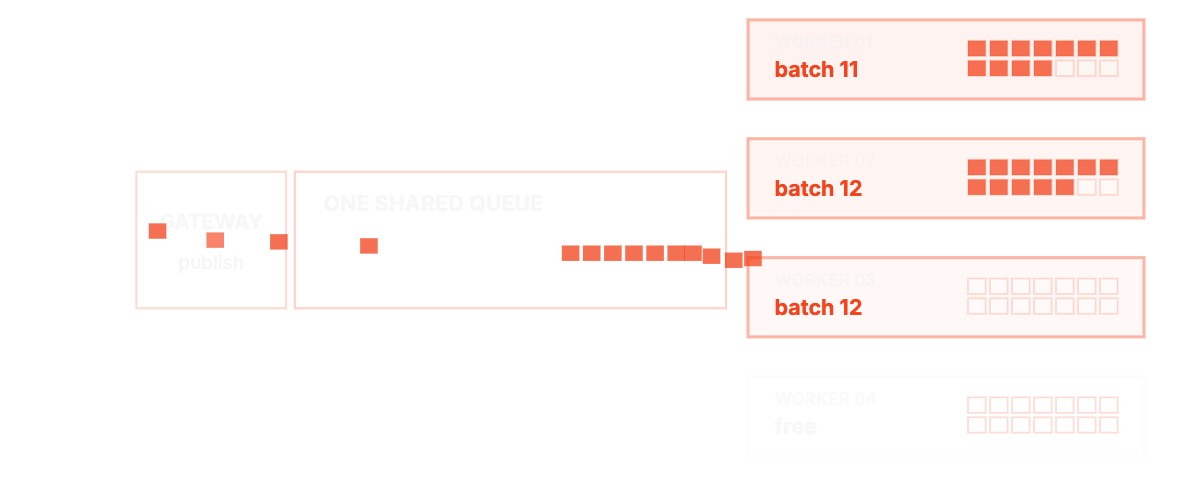
Your team just upgraded to Claude Opus 4.8 with 1M context. First decision: scrap the retrieval layer entirely and shove the entire 400k token knowledge base into the system prompt to be "safe." Two weeks later, the agent starts hallucinating, calling the wrong tools, and API bills quadruple. The model didn't get weaker. The context got dirty.
This is the biggest trap of 2026. Claude Opus 4.8, Gemini 3.5, and DeepSeek V4 have all hit the 1M token mark. However, statistics from production teams still show: over 70% of LLM application errors stem from incorrect, missing, or messy context — not the model. Worse, Anthropic's research shows that context exceeding 100k tokens begins to degrade reasoning quality. A larger window doesn't mean you should fill it.
Why "stuffing everything into context" fails
Three reasons, all based on physics, not opinion.
Lost-in-the-middle. The model pays most attention to the beginning and end of the context. Important documentation buried at token 300k in a pile of logs? High probability of being ignored. This is an attention characteristic, not a bug that will be patched.
Linear cost per token. Every turn, you pay for the entire context — including the 350k tokens the model doesn't even use. Running an agent for 50 turns with a 500k context is an extremely efficient way to burn budget.
Reasoning degrades after 100k. The model can still "read," but multi-step reasoning capabilities over that context pile drop significantly. This means: retrieval is still necessary, even with 1M context. Large windows are for holding long conversation histories and truly relevant documents — not for replacing selection.
Correct mindset: the context window is RAM, not a hard drive. No one loads an entire hard drive into RAM and expects the CPU to find what it needs.
The four layers of a proper context system
Context engineering is not about writing good prompts. It is a four-layer architecture that decides what enters "RAM" at any given time.
1. Knowledge retrieval. RAG is not dead — it has changed roles. Instead of retrieving due to small context, it now retrieves to keep context clean. For domains with complex relationships (product – customer – contract), GraphRAG outperforms pure vector search; 2026 production benchmarks show that agentic RAG combined with knowledge graph significantly reduces hallucination, at the cost of more complex orchestration.
2. Memory. Short-term is the current session history. Long-term is what the agent needs to remember across multiple sessions: user preferences, past decisions, learned facts. These two require different mechanisms — mixing them is a recipe for context bloat.
3. Orchestration. The layer that decides what goes into the context, in what order, and in what format. For the same data, providing it in a concise markdown table format usually outperforms pasting a raw 5k token JSON.
4. Dynamic tool loadout. Do not declare 80 tools for every request. Select tools based on the query — load only 5-10 relevant tools — improving function-calling accuracy by about 44%. MCP registries now have tens of thousands of servers; selective discipline is more important than ever.
Pruning techniques for long-running agents
Agents running 100+ turns will pollute their own context if you do not intervene. Three techniques have become standard:
Summarize-and-truncate. Keep the last N turns and compress older parts into a summary. Key point: the summary must retain decisions and constraints, not the conversation flow.
def compact_history(messages, keep_recent=10, budget=8_000):
    old, recent = messages[:-keep_recent], messages[-keep_recent:]
    if count_tokens(old) < budget:
        return messages
    summary = llm.summarize(
        old,
        instruction="Giữ: quyết định đã chốt, ràng buộc, ID/số liệu. Bỏ: diễn giải."
    )
    return [{"role": "system", "content": f"Tóm tắt trước đó:\n{summary}"}] + recent
Checkpointing state. LangGraph checkpoints the entire graph state after each step. Agent crashes at turn 40? Resume from the checkpoint instead of replaying the entire history — both cheaper and cleaner.
Letta-style virtual context. Idea borrowed from operating systems: the context window is "main memory," the rest resides in "external storage," and the agent performs page in/out via tool calls when needed. The agent decides what is worth keeping in RAM — exactly how an OS manages virtual memory.
Long-term memory: when to use a framework vs. when a SQL table suffices.
This is where many teams over-engineer. Quick comparison:
| Solution | Suitable when | Not suitable when |
|---|---|---|
Table user_preferences |
Structured facts, few, clear schema (language, timezone, tier) | Unstructured knowledge, self-learning |
| LangGraph checkpointing | Session state, workflow resume, already used LangGraph | Cross-session, cross-agent memory |
| Mem0 | Cross-session conversational memory, auto-extract facts from chat | Need tight control over what is remembered |
| Letta | Long-running agents, self-managed memory, virtual context | Simple use case, small team |
Rough rule: if you can pre-list what needs to be remembered, use a SQL table. If the agent must learn from interaction what it needs to remember, only then consider Mem0 or Letta. Many enterprise "memory systems" are actually just 15 lines of preferences — and that is enough.
Measurement: token budget as an SLO
What cannot be measured will bloat. Two metrics to track from day one:
- Token budget per-turn. Set a threshold (e.g., 30k/turn) and alert when exceeded — treat it like a latency SLO. Exceeding budget is often an early symptom of context leakage: tool output is not truncated, history is not compressed.
- Effective context utilization ratio. Sample responses, check how much context actually contributes to the answer (LLM-as-judge does this well). If 80% of the context is ballast, your retrieval is broken — and you are paying for that failure on every request.
Notably: the 2026 agent engineering survey shows 89% of production teams have observability, but only 52% have evals. Measuring tokens without quality evals means you are only halfway there.
Conclusion
The 1M token race is a race for labs. Your race is different: putting the right 20k tokens in the right place, at the right time. The best model in 2026 with dirty context will still lose to an average model with clean context — and no upcoming upgrade will change that, because the problem is not the model. It is the discipline of the data provider.